Papers
Browse the full research library.
Ten papers per page, with summaries, diagrams, formulas, concepts and citations kept close to the source.
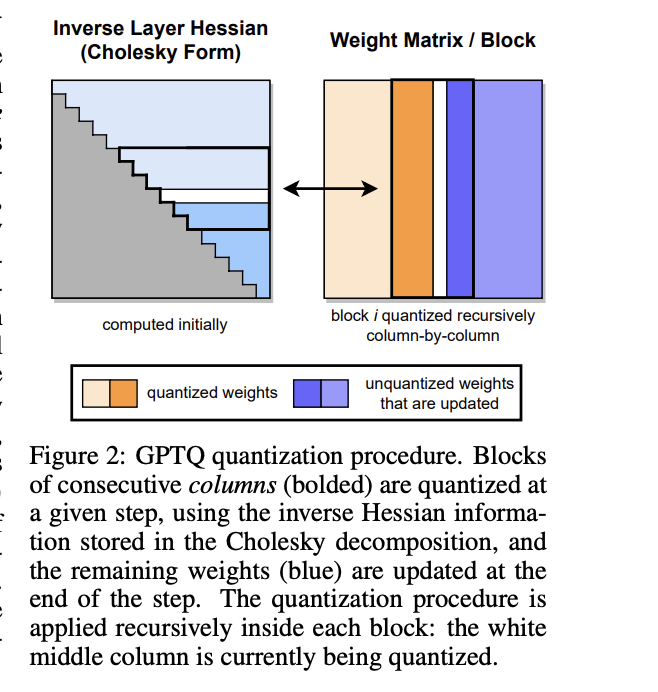
GPTQ
A one-shot, approximate second-order post-training quantization method that compresses 175B-scale language models to 3–4 bits with minimal accuracy loss.
Essential for understanding modern weight-only PTQ: Hessian-aware error compensation, 3–4 bit compression, group size trade-offs, and memory-bandwidth-limited LLM inference.
Elias Frantar, Saleh Ashkboos, Torsten Hoefler
Read paper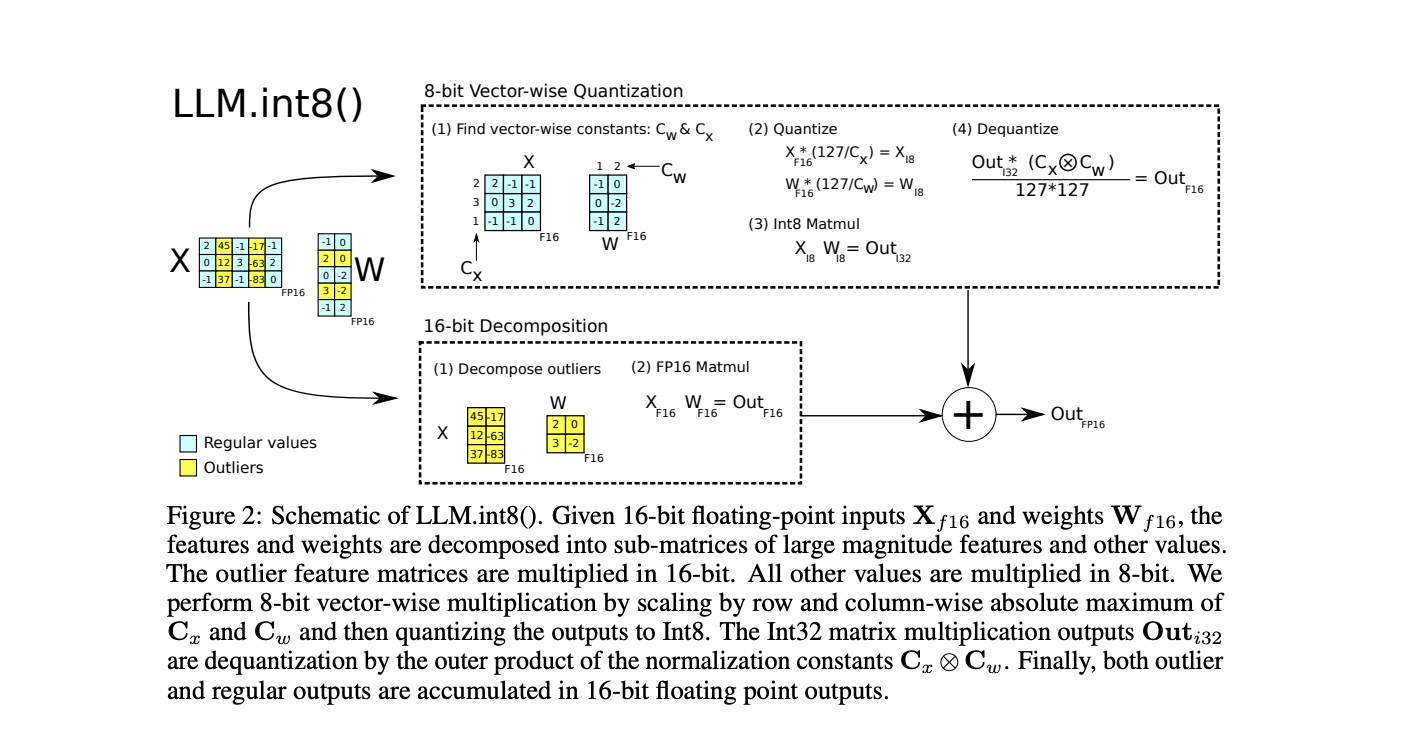
LLM.int8()
An outlier-aware INT8 matrix multiplication method that enables large Transformer inference with near-full-precision accuracy.
A foundational paper for understanding INT8 LLM inference, activation outliers, mixed precision, and memory-efficient deployment.
Tim Dettmers, Mike Lewis, Younes Belkada
Read paper