MachinoAI Research
Claude Opus 5.5: What It Does Well, Where It Still Falls Short
Opus 5.5 has a compelling capability-efficiency profile, but external testing shows why benchmark strength should not be confused with universal reliability.
TL;DR
The strongest documented story is sustained coding and knowledge work with lower token use and cost. The less comfortable story is that independent workloads still expose failures: Sonar found a near-flat functional pass rate versus Opus 5, while Endor Labs reported 33.5% secure-code pass on its own benchmark and flagged training-recall cases.
Why It Matters
A model can be excellent at completing large tasks while still needing downstream verification. The useful question is not whether Opus 5.5 is “good” in the abstract, but where its failure modes fit your workload, harness, security controls, and tolerance for review.
Research Brief
The shortest useful explanation.
The strongest documented story is sustained coding and knowledge work with lower token use and cost. The less comfortable story is that independent workloads still expose failures: Sonar found a near-flat functional pass rate versus Opus 5, while Endor Labs reported 33.5% secure-code pass on its own benchmark and flagged training-recall cases.
Core Explanation
A balanced model review that separates documented strengths from real limitations, using Anthropic’s release data plus independent coding, security, and hands-on comparisons.
Why It Matters
A model can be excellent at completing large tasks while still needing downstream verification. The useful question is not whether Opus 5.5 is “good” in the abstract, but where its failure modes fit your workload, harness, security controls, and tolerance for review.
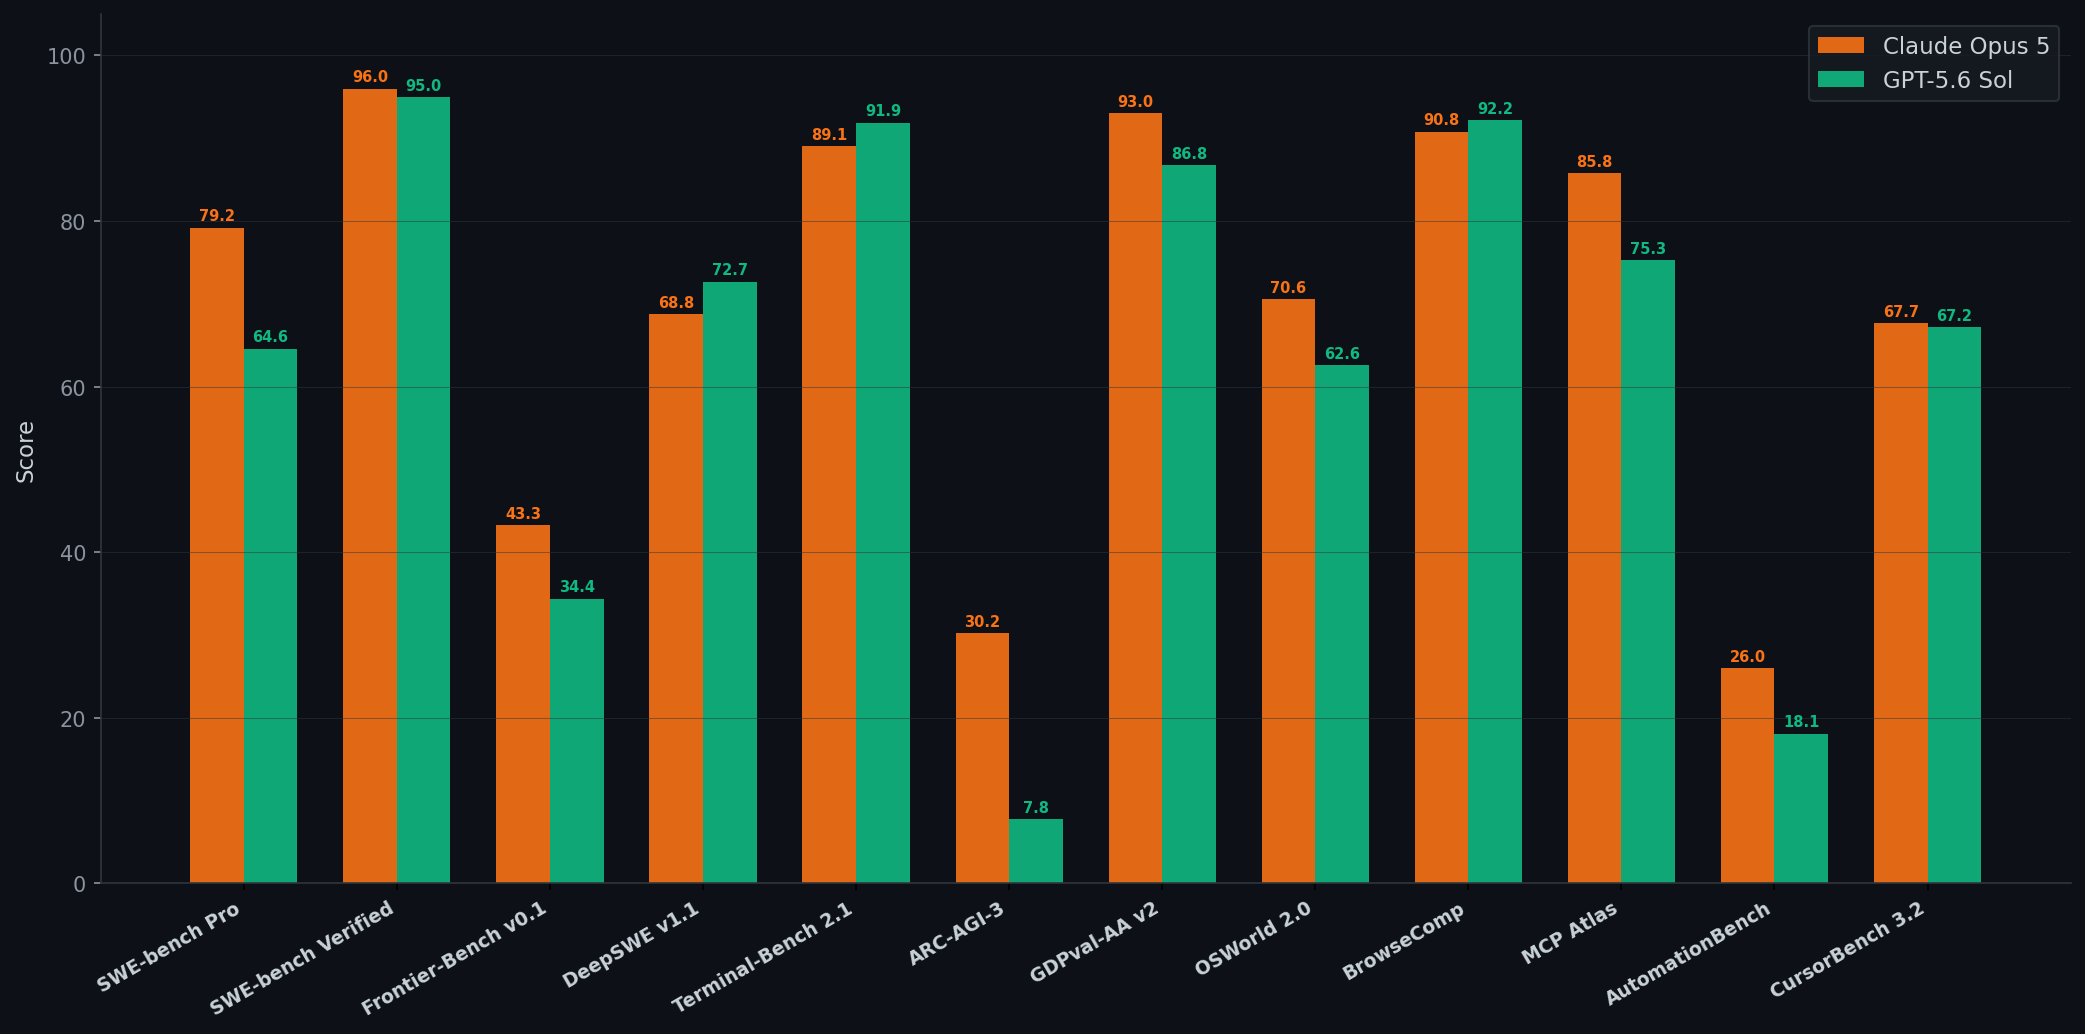
Opus 5 vs GPT-5.6 Sol benchmark visual
Third-party benchmark visualization of Claude Opus 5 versus GPT-5.6 Sol, used as historical competitive context rather than as an Opus 5.5 benchmark.
References
Introducing Claude Opus 5.5
Launch claims and official benchmark/safety context.
Claude Opus 5.5: An evaluation review and metrics benchmarks
Independent coding-quality evaluation.
Opus 5.5: 6x cheaper and 2x faster than Fable 5.1, but only 33.5% of code is secure
Independent agent-security benchmark with functional, secure-code and memorization findings.
Claude Opus 5.5 vs GPT-6 Sol: the same storm in 3D
Single hands-on comparison of Claude Code with Opus 5.5 versus Codex with GPT-6 Sol.
Claude Opus 5.5 model documentation
Current family comparison, pricing and capability specifications.
Anthropic — Claude Opus 5.5Sonar evaluation of Opus 5.5Endor Labs — Opus 5.5 security evaluationGekkode — Opus 5.5 vs GPT-6 Sol 3D testOpus 5 vs GPT-5.6 Sol benchmark visual