MachinoAI Research
Retrieval-Augmented Generation for Large Language Models: A Survey
A systematic survey organizing RAG architectures, training strategies, applications, evaluation, and open challenges.
TL;DR
RAG is decomposed into retrieval, augmentation, and generation, with a progression from simple pipelines to modular systems.
Why It Matters
It provides a taxonomy for reasoning about RAG system design and the failure modes of knowledge-grounded generation.
Research Brief
The shortest useful explanation.
RAG is decomposed into retrieval, augmentation, and generation, with a progression from simple pipelines to modular systems.
Core Explanation
A systematic survey organizing RAG architectures, training strategies, applications, evaluation, and open challenges.
Why It Matters
It provides a taxonomy for reasoning about RAG system design and the failure modes of knowledge-grounded generation.
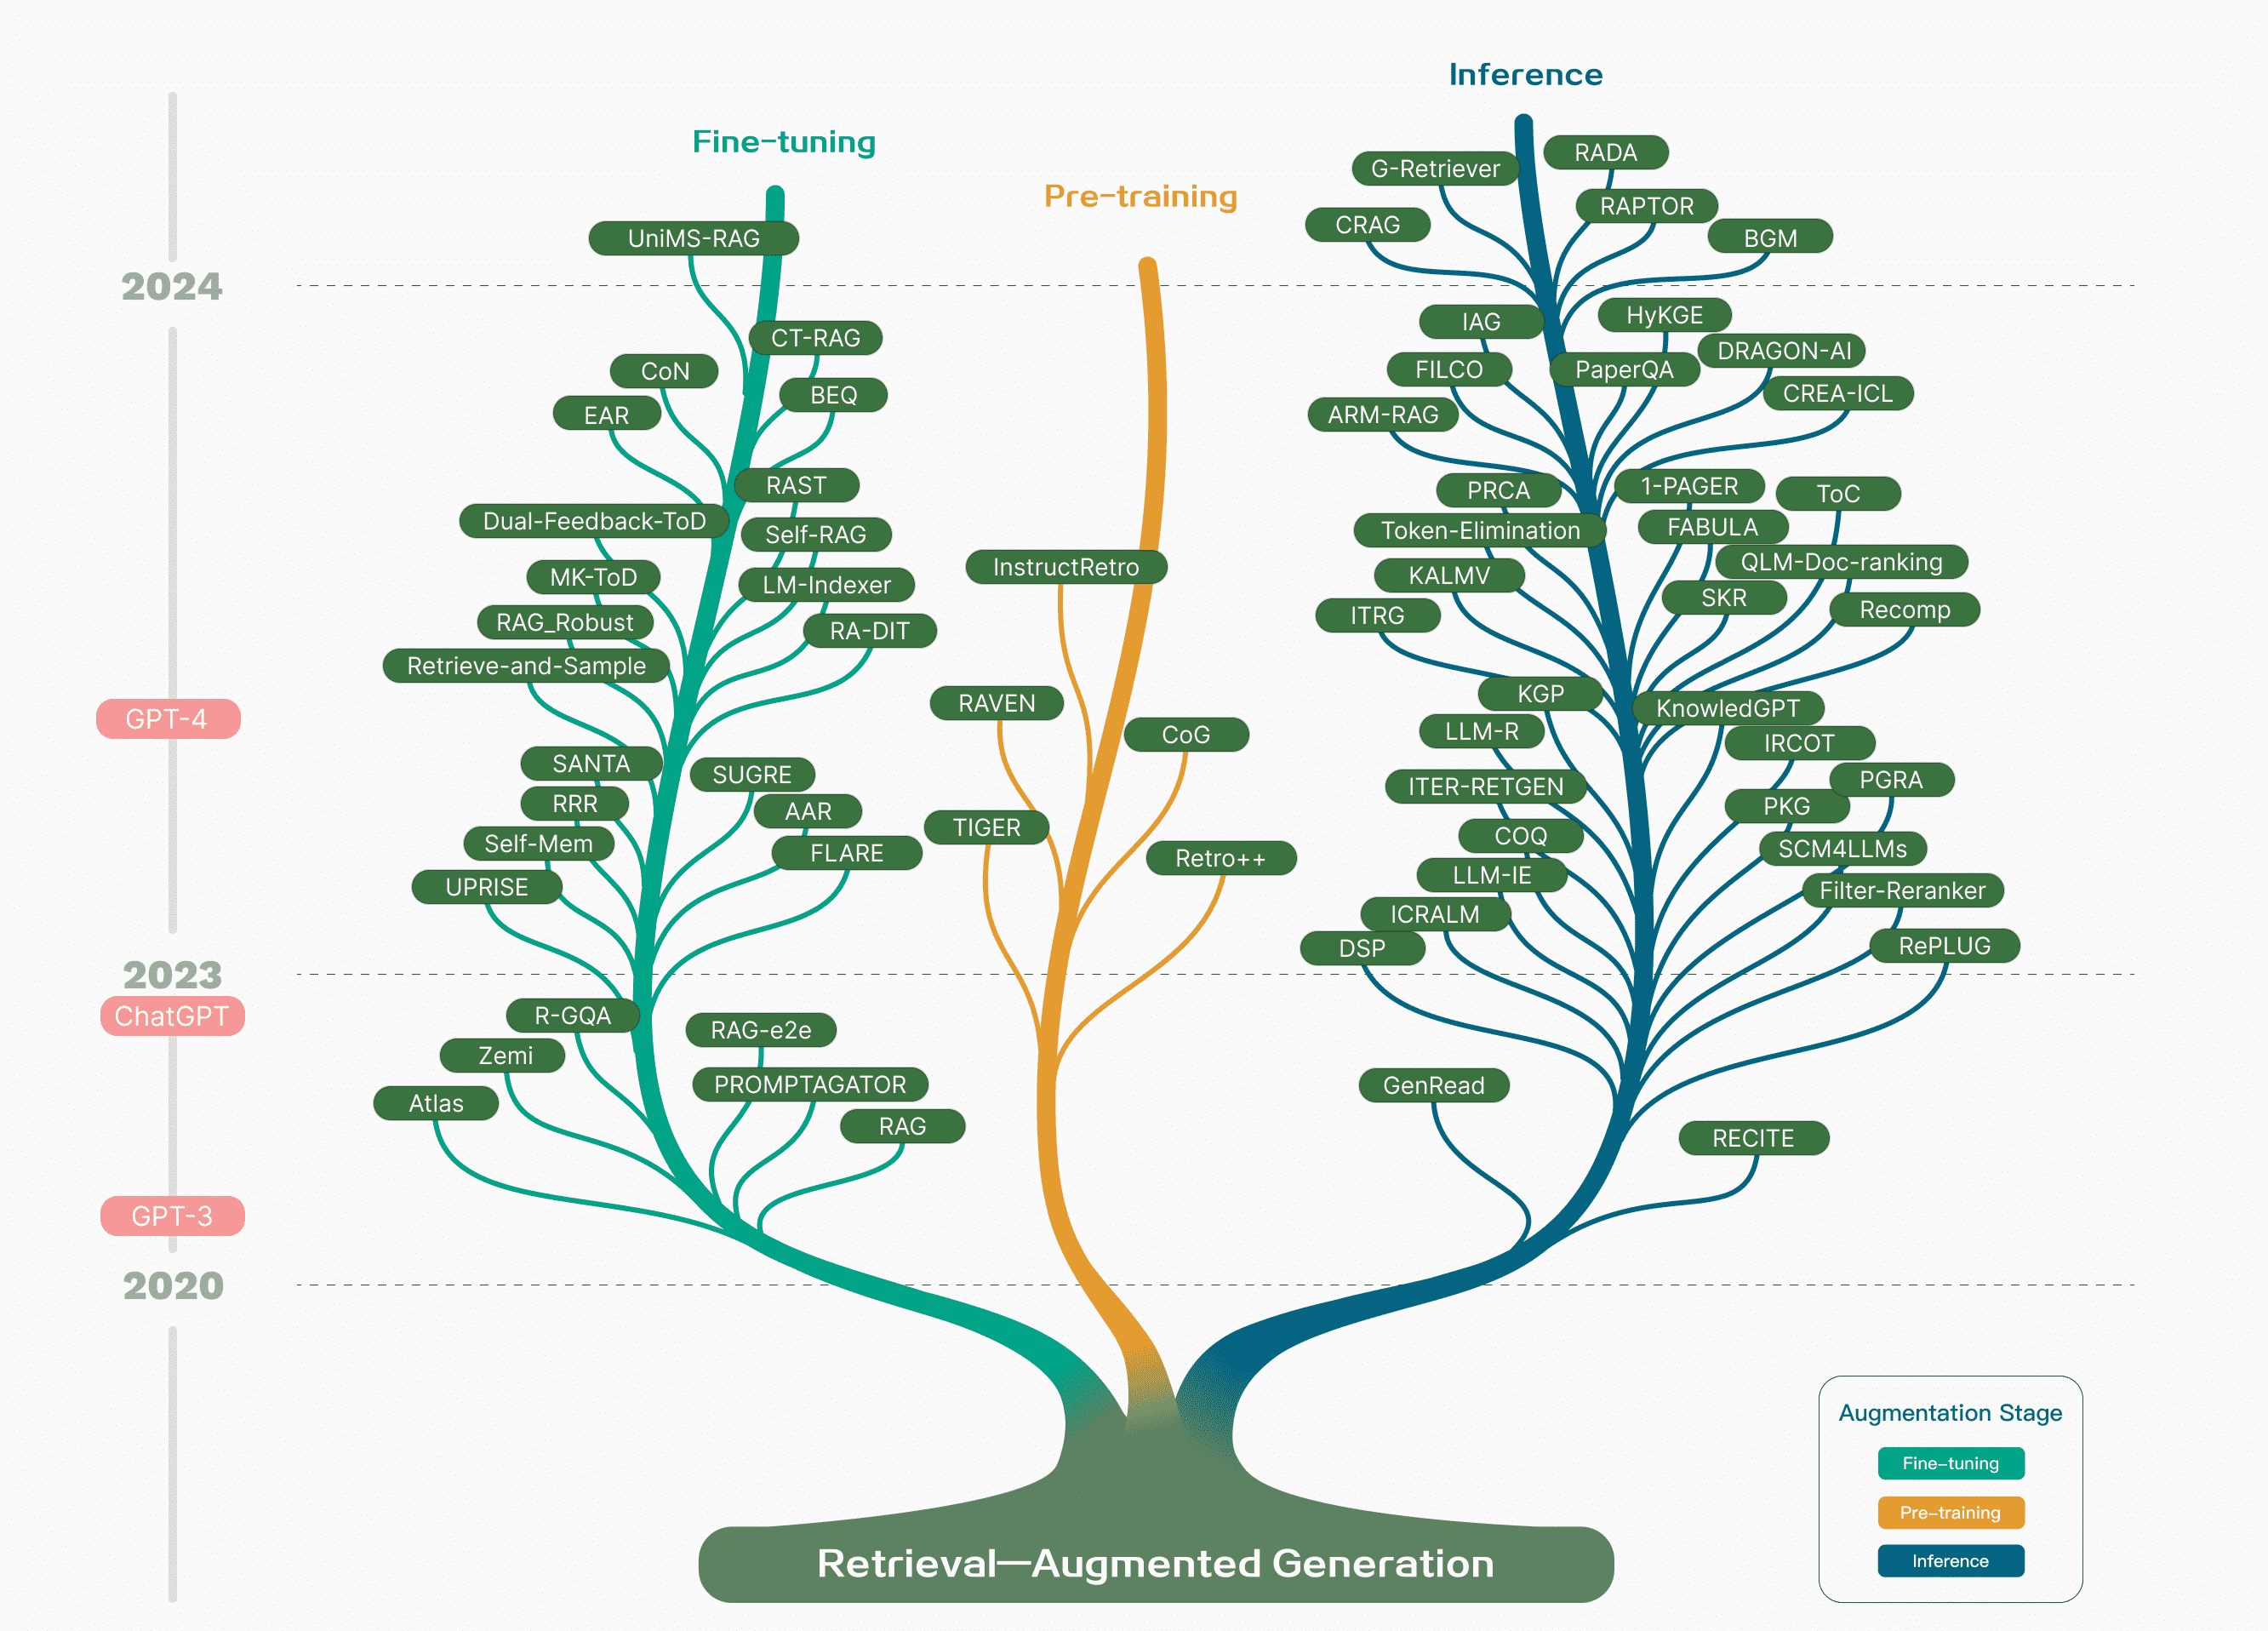
Figure 1: Technology Tree of RAG Research
Original Figure 1 from the RAG survey showing the technology tree of RAG research across pre-training, fine-tuning, and inference stages.
Section 01
The Problem
Single-shot language-model responses are insufficient when a task requires persistent state, external evidence, multi-step reasoning, computation, or controlled actions.
Section 02
The Big Idea
Augment the language model with explicit capabilities outside the base model: retrieval, memory, tools, planning, or a governed execution environment depending on the paper.
Section 03
How It Works
The workflow is iterative: receive state, decide on the next action, call retrieval or a tool, observe the result, update context, and continue until the task can be completed.
Section 04
The Math
The core mathematics is mainly the standard machinery behind embeddings, similarity, probability, optimization, and evaluation. The key is to connect each mathematical operation to the system component it enables.
Section 05
Architecture
Reusable architecture: task input -> model/planner -> memory or retrieval -> tool/environment -> observation -> state update -> next action -> final output.
Section 06
Experiments
Validation uses task-specific benchmarks or controlled simulations. Agentic Reasoning evaluates scientific reasoning and deep-research tasks; PaperQA evaluates scientific QA including LitQA; the RAG survey organizes published evaluation practice; Generative Agents evaluates believable behavior and component ablations; MIRA evaluates complete clinical workflows against physician cohorts.
Section 07
What We Learned
System-level capability depends on orchestration of models, retrieval, memory, tools, and evaluation—not prompting alone. Limitations include benchmark dependence, retrieval quality, evaluator bias, simulated environments, and lack of prospective deployment.
Section 08
What Came Next
These ideas feed into research agents, persistent-memory agents, RAG pipelines, tool-use systems, and domain-specific autonomous workflows. Next study state management, tool contracts, retrieval quality, evaluation, observability, retries, permissions, and human-in-the-loop controls.
Section 09
Engineering Takeaways
Build the model as one component of a larger stateful system. Make tool calls typed and observable; separate durable state from transient context; measure retrieval and tool-selection quality independently; design explicit failure and retry paths; and constrain high-impact actions with permissions and human approval.
Formulas
Retrieval similarity
Rank candidate documents by similarity between the query embedding and document embedding.