Papers
Browse the full research library.
Ten papers per page, with summaries, diagrams, formulas, concepts and citations kept close to the source.
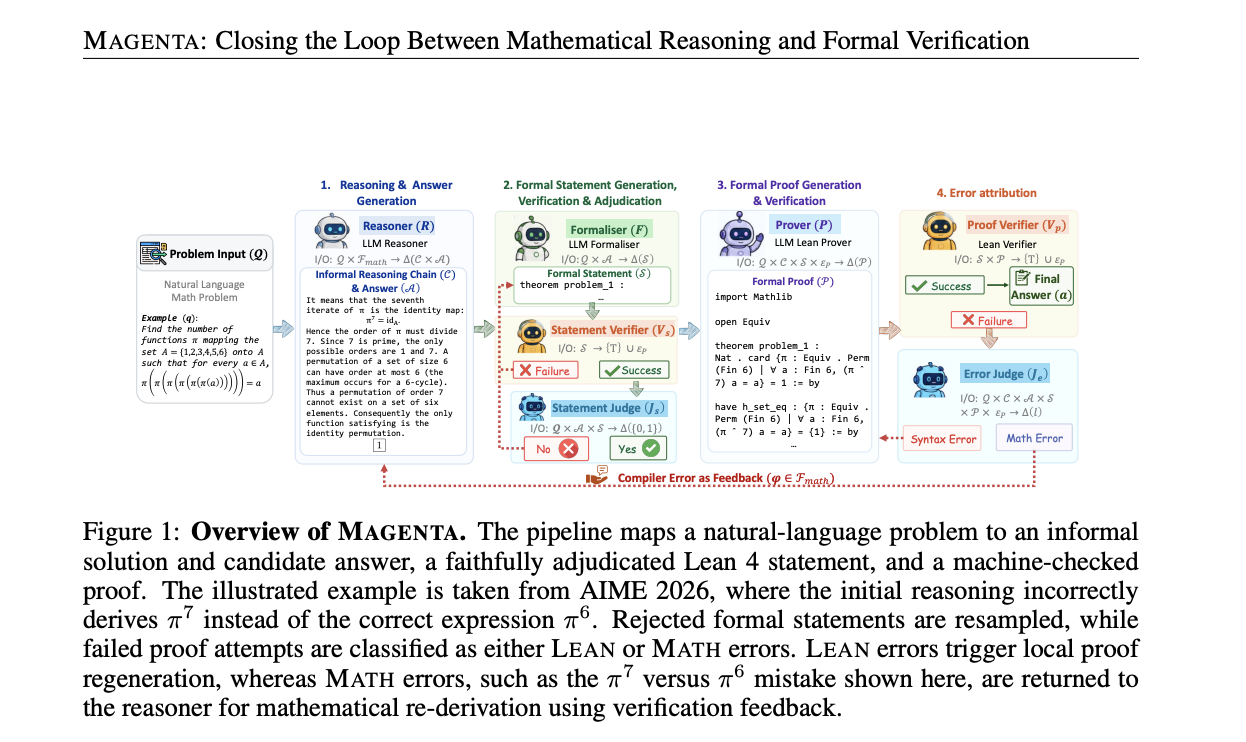
Magenta
Verification-guided mathematical reasoning with Lean 4.
Useful for verifier-guided agents, formal correctness boundaries, and test-time compute trade-offs.
Joshua Ong Jun Leang, Haonan Li, Zheng Zhao
Read paper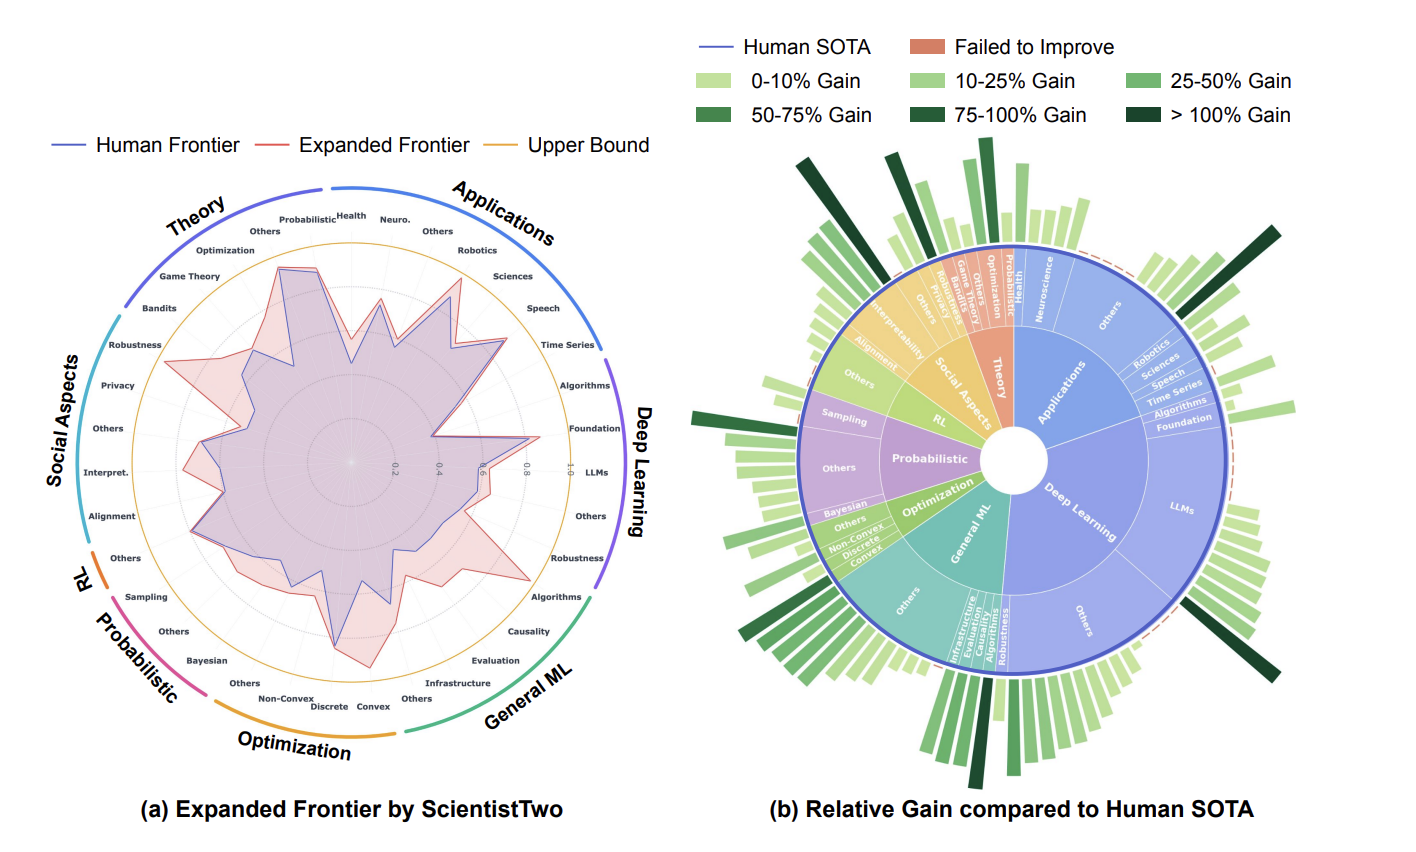
ScientistTwo
Autonomous ML research with explicit experiment, ablation and review loops.
Understand what a production autonomous research workflow needs beyond a single agent.
Jaehyun Nam, Jinsung Yoon, Yanzhou Pan
Read paper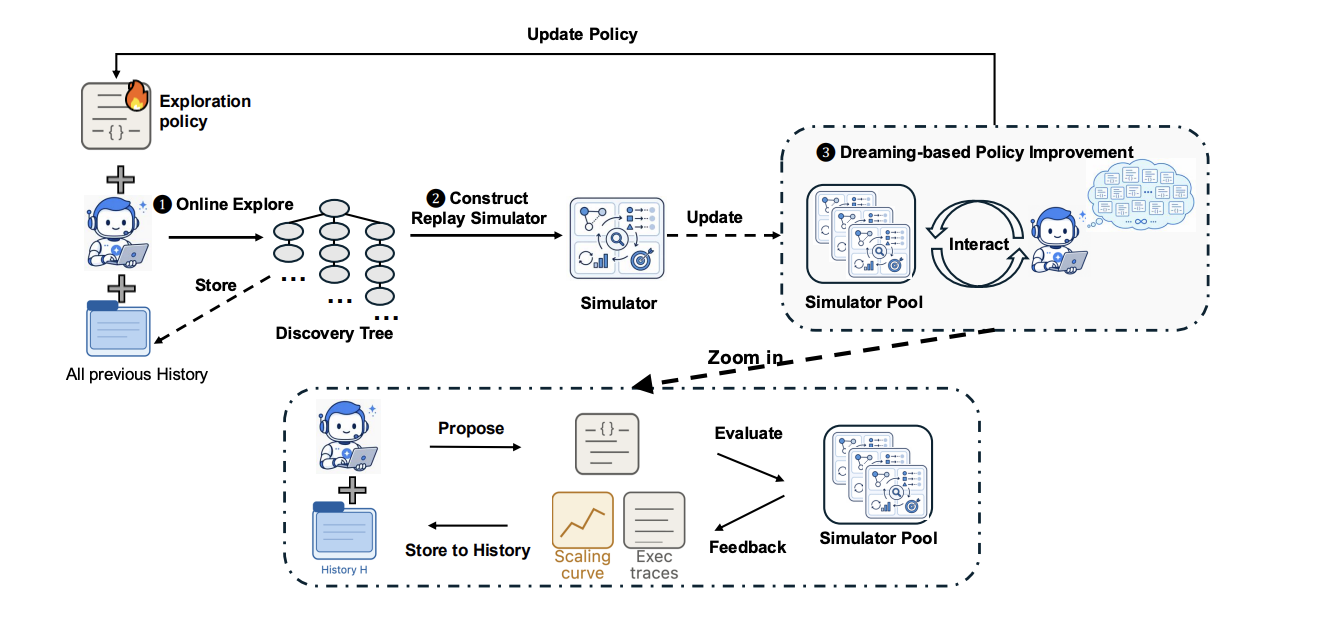
Dream-RSI
Replay-based optimization of agent exploration policies.
Understand offline evaluation for self-improving agent controllers.
Tong Zheng, Xidong Wu, Zheng Zhang
Read paper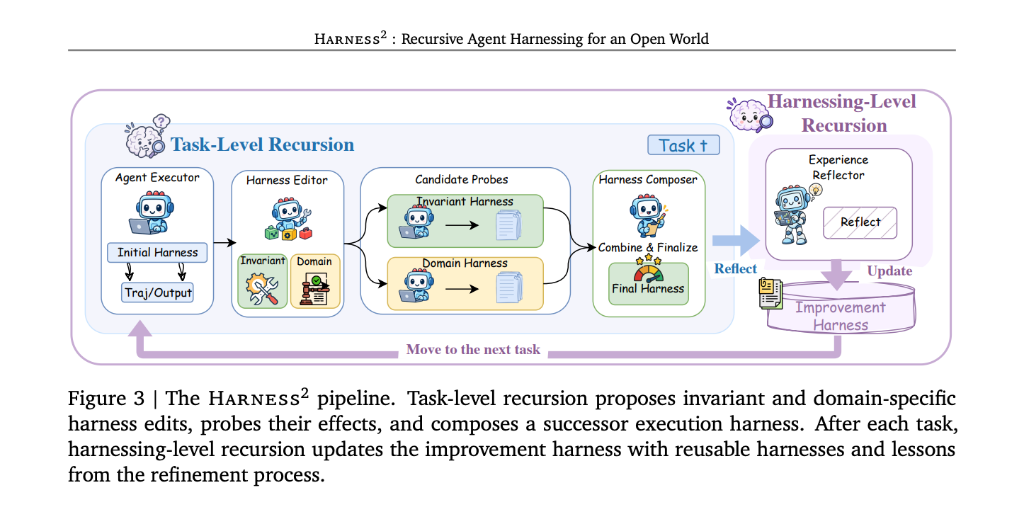
RRSI
Production-oriented agent harness evolution with transfer-aware regularization.
Best starting point for understanding safe and cost-aware harness optimization.
Peng Xia, Rujun Han, Zifeng Wang
Read paper
Opus 5.5
Opus 5.5 is a 1M-context, adaptive-thinking model optimized for long-running agents. The release’s standout theme is cost-adjusted capability: stronger task completion with lower per-token prices, lower token consumption, and faster generation, alongside production safeguards for high-risk workloads.
Read this to understand what changed from Opus 5 to Opus 5.5, how to interpret the benchmark and cost numbers, what adaptive thinking means operationally, and which production agent architectures benefit from lower token and tool-call overhead.
Anthropic
Read paper
BATS
Agent scaling is not just more tokens or tool calls; agents must know and strategically allocate their remaining budget.
Read this if you design production agents where latency, API spend, tool-call limits, and verification quality must be controlled together.
Tengxiao Liu, Zifeng Wang, Jin Miao
Read paper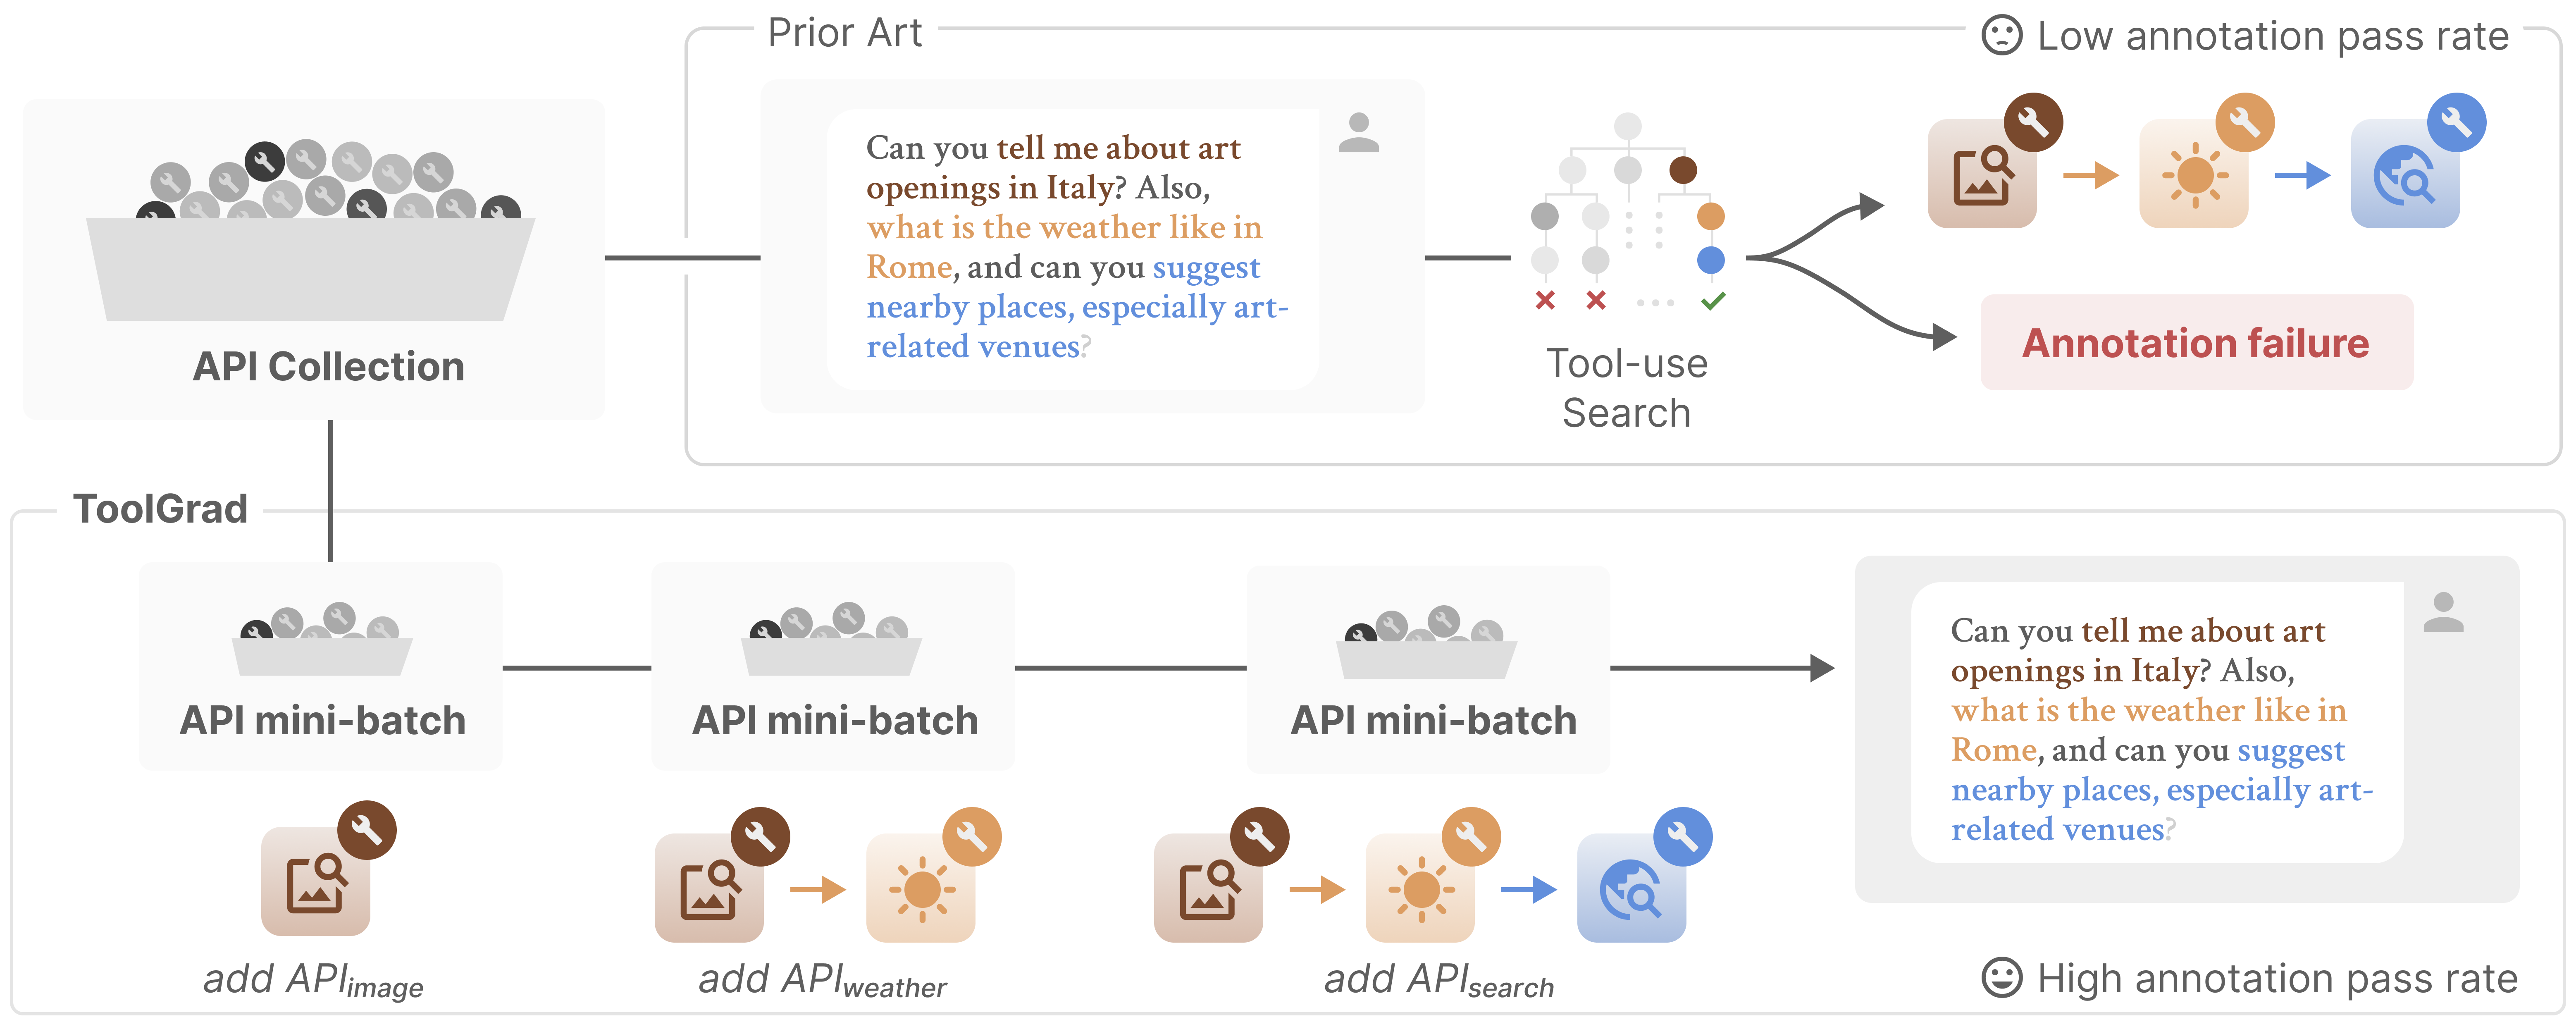
ToolGrad
Generate the successful tool-use workflow first, then synthesize the user query around it.
Read this if you build function-calling agents, tool routers, agent training pipelines, or synthetic-data systems.
Zhongyi Zhou, Kohei Uehara, Haoyu Zhang
Read paper
ReasoningBank
ReasoningBank turns agent successes and failures into reusable reasoning strategies that improve future tasks without updating model weights.
Read this if you are designing agent memory, long-running agents, test-time learning, or systems that need to improve from operational experience.
Siru Ouyang, Jun Yan, I-Hung Hsu
Read paper
MIRA
MIRA is an autonomous medical agent evaluated in a sandboxed EHR workflow with tools for diagnosis, testing, treatment, and admission decisions.
Relevant to enterprise agent design because the system combines an LLM, many tools, structured APIs, safety evaluation, and workflow state.
Dyke Ferber, Lars Hilgers, Christiane Höper
Read paper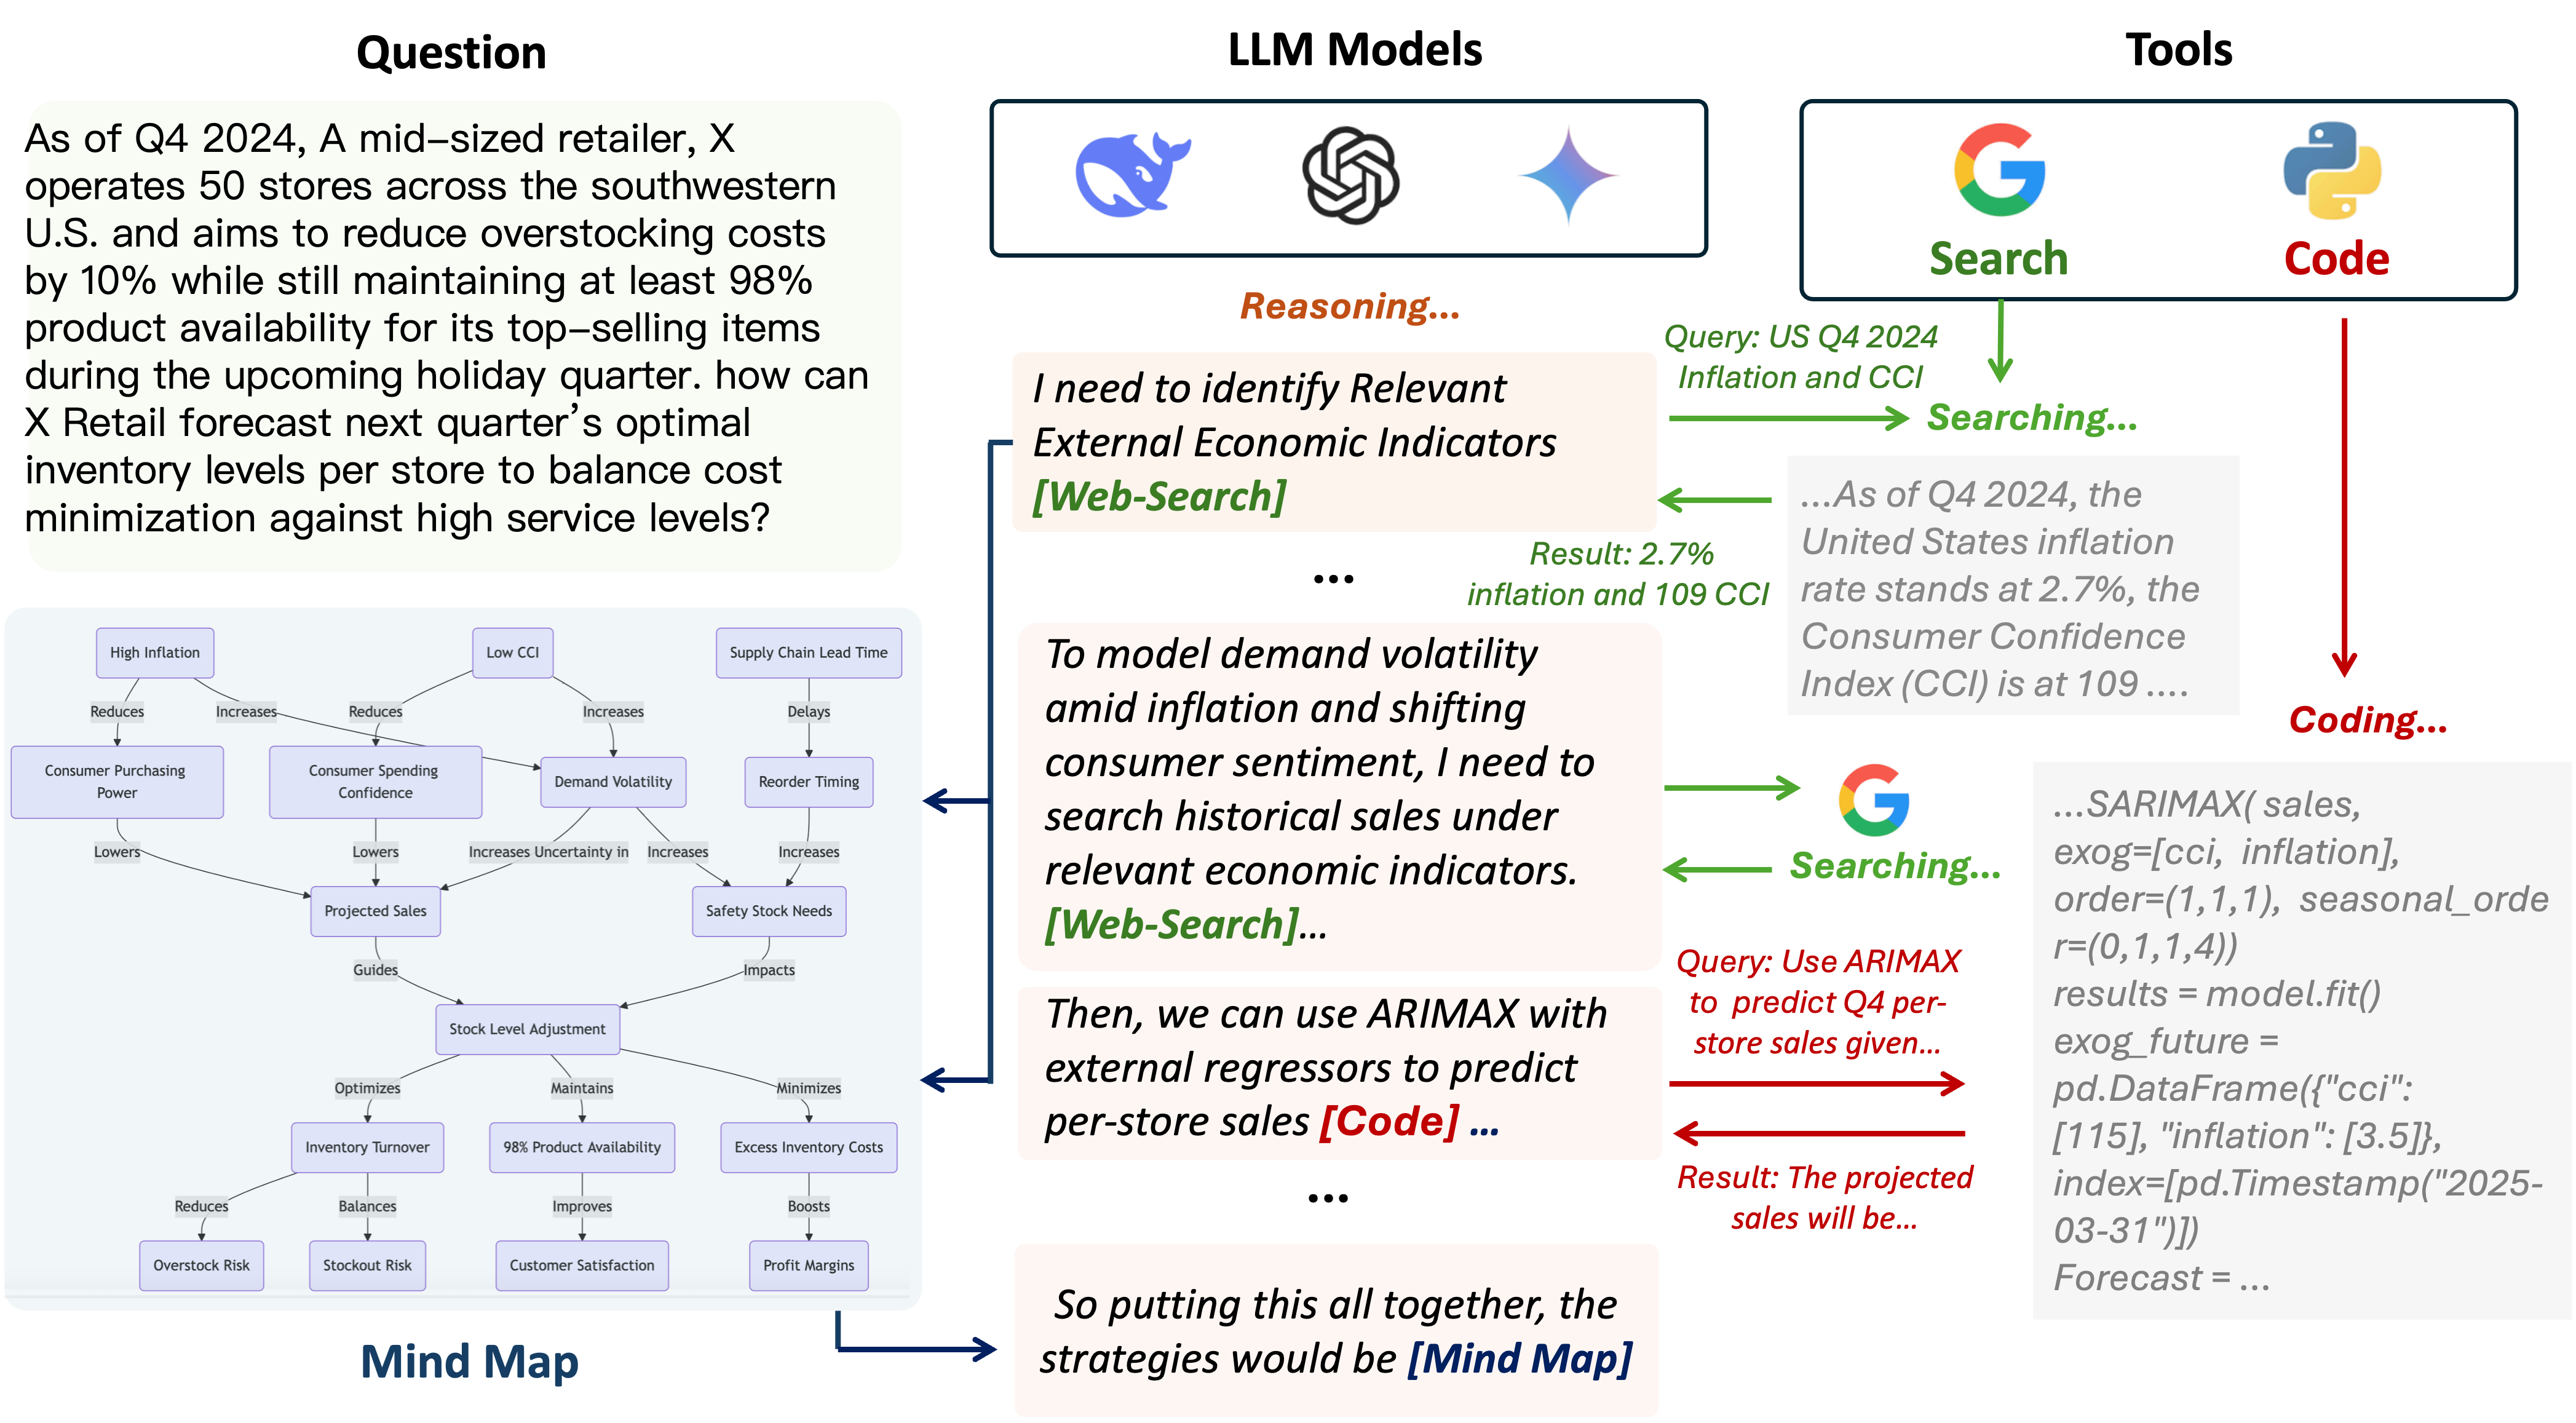
Agentic Reasoning
A tool-using agent framework that extends LLM reasoning with web search, coding, and structured reasoning memory for deep research tasks.
Useful for understanding how deep-research agents combine model reasoning with tools and structured intermediate state.
Junde Wu, Jiayuan Zhu, Yuyuan Liu
Read paper