Papers
Browse the full research library.
Ten papers per page, with summaries, diagrams, formulas, concepts and citations kept close to the source.
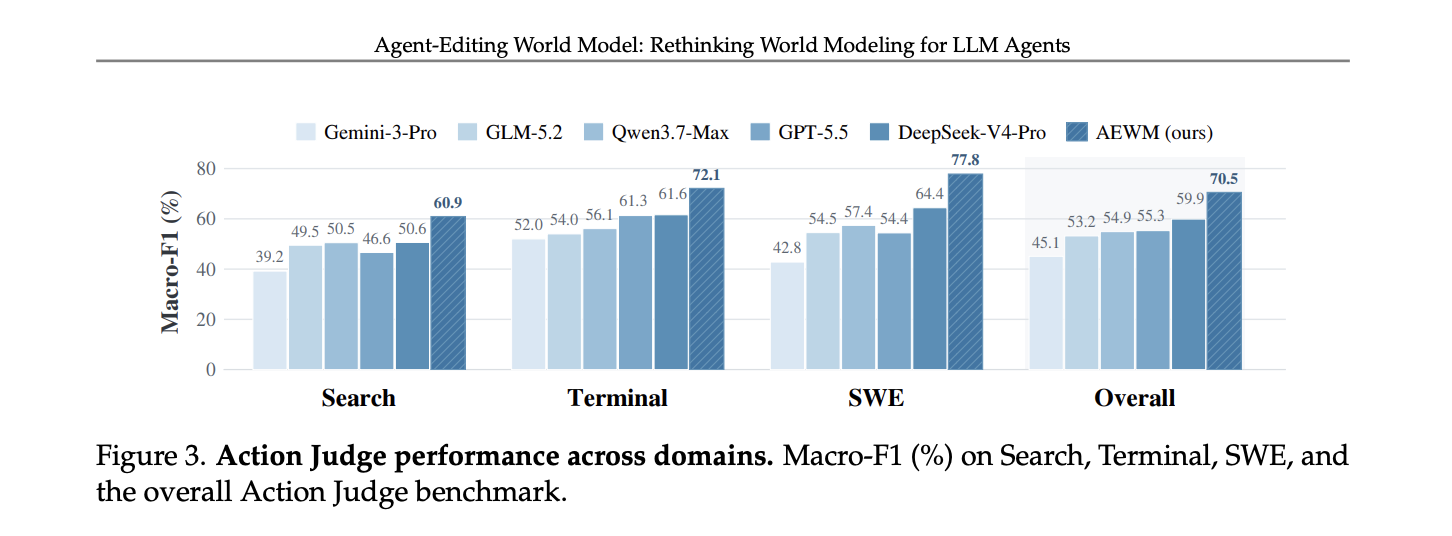
Agent-Editing World Model
AEWM turns world modeling into agent-state judgment and revision: keep useful decisions, edit noisy ones, then ground the trajectory with real execution.
Read this to understand a different design axis for agent reliability: instead of adding another critic or simulating tool outputs, learn when a proposed reasoning-action state is harmful and replace it before execution.
Shuang Sun, Guoxin Chen, Fanzhe Meng
Read paper
Jev AI
Jev is TypeSafe AI’s first System One Model: state in, typed probabilistic decisions out.
A technical deep dive into the System One idea, RLCD, typed decisions, calibration, production architecture, benchmarks, and limitations.
Diogo Almeida, TypeSafe AI
Read paper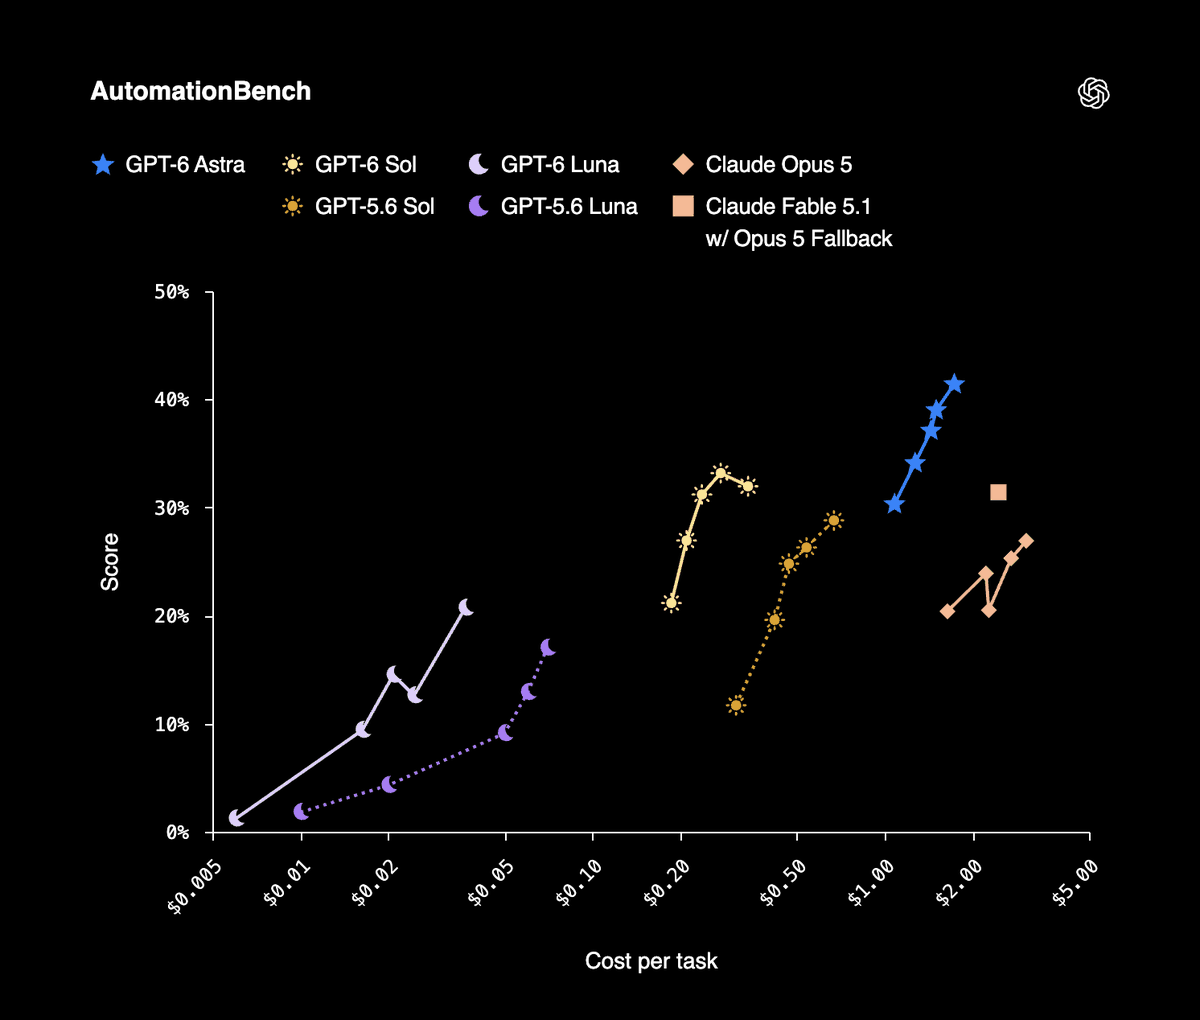
GPT-6 Sol
A source-grounded deep dive into GPT-6 Sol covering model behavior, API/runtime design, benchmarks, effort economics, safety, limitations, and production agent architecture.
Read this to understand what GPT-6 Sol actually exposes, what OpenAI has disclosed about its development, how its benchmark results should be interpreted, and how to design a production agent around its reasoning/cost trade-offs.
OpenAI
Read paper
Grok 4.7 — Long-Horizon Agents
A source-grounded technical walkthrough of Grok 4.7 training changes, runtime controls, multimodal input, tool use, context management and long-horizon agent engineering.
Read this to understand what SpaceXAI says changed in Grok 4.7, what is public versus proprietary, and how its API/runtime design maps to long-running agents.
SpaceXAI
Read paper
Grok 4.7 — Benchmarks
A provenance-first benchmark dossier for Grok 4.7, preserving the official comparison matrix and separating it from Artificial Analysis measurements.
Read this when you need to interpret Grok 4.7 launch numbers without mixing vendor runs, independent runs, benchmark versions, effort tiers or harnesses.
SpaceXAI, Artificial Analysis
Read paper
Grok 4.7 — Production
A systems-oriented deployment guide covering the Grok 4.7 API, agent loop, caching, long-context economics, rate limits, observability and safety boundaries.
Read this to design a production-grade Grok 4.7 agent service rather than treating the model as a stateless chat endpoint.
SpaceXAI
Read paper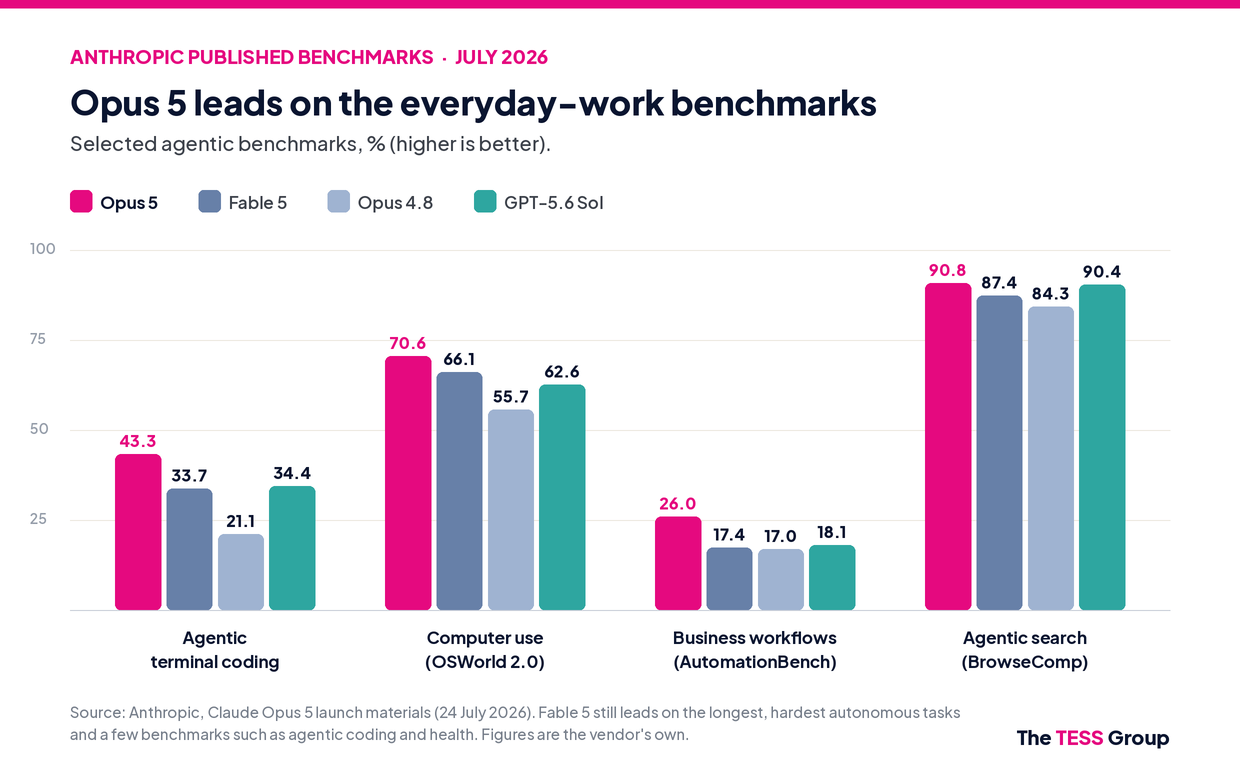
Opus 5.5 — Production Economics
Production economics view: compare unit price, task trajectory, code volume, review effort, and verification cost.
Read this when deciding whether Opus 5.5 changes the economics of a production agent or coding workflow.
Anthropic, Sonar, Endor Labs
Read paper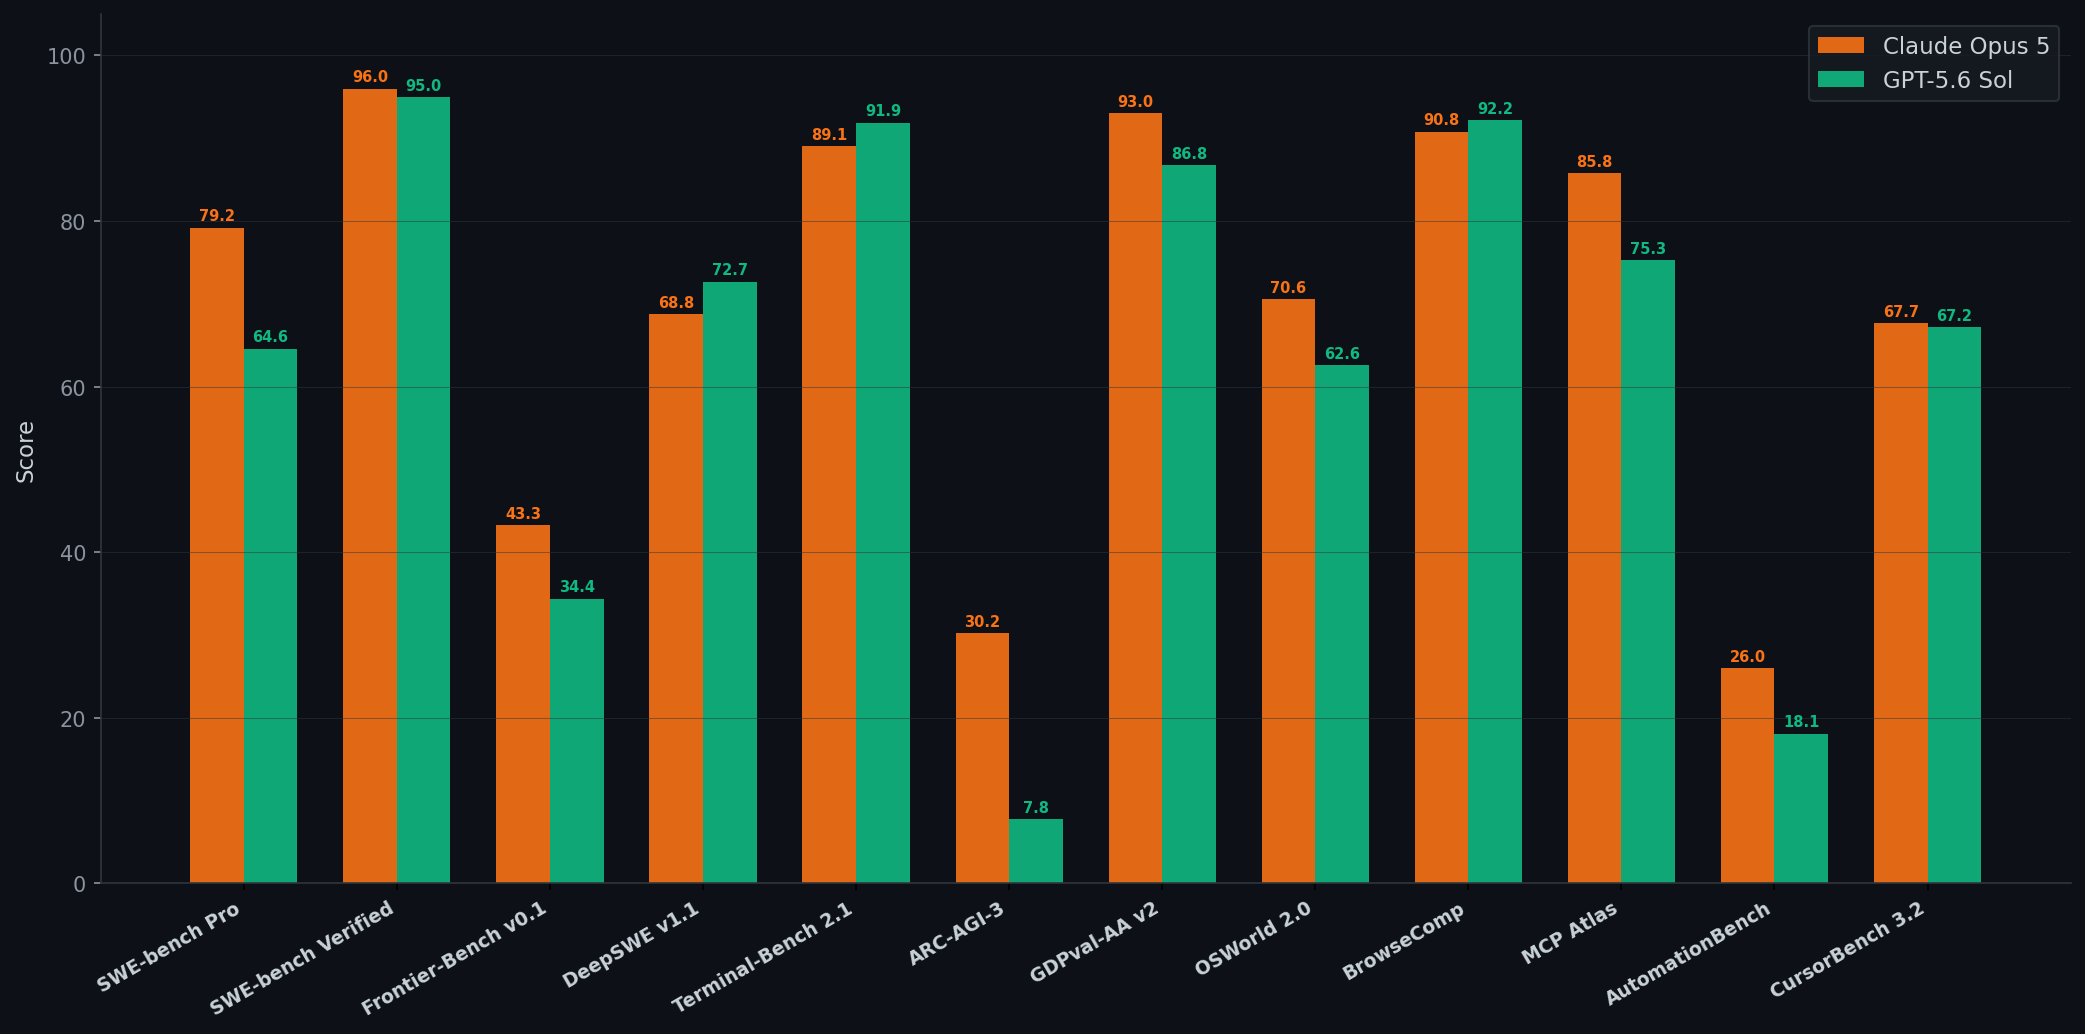
Opus 5.5 — Strengths & Limits
Strengths and limitations with explicit separation between Anthropic claims, independent measurements, and model-review observations.
Read this for the uncomfortable details that a vendor benchmark page cannot answer by itself.
Anthropic, Sonar, Endor Labs
Read paper
Opus 5.5 — What Changed
A plain-English model overview focused on what changed from Opus 5 and what those changes mean in daily use.
Read this for the clean product-level picture before diving into benchmarks or deployment details.
Anthropic
Read paper
AgentActionBench
A process-level benchmark for reliable research-agent execution.
Useful for designing evals for coding and research agents where execution, reproducibility, and traceability matter.
Hanhua Hong, Yizhi Li, Luu Gia Huy
Read paper